Latest · newest first60
28 Oct33
BrilliantHaloLabs Brilliant Labs Unveils Halo AI Glasses With Full-Color Micro-OLED, On-Device AI, and Open-Source ArchitectureOn October 27, Singapore-based smart glasses maker Brilliant Labs unveiled its new Halo AI glasses, priced at $399. The device features a full-color Micro-OLED display, a long-term-memory AI assistant, and an adaptive gaming experience called Narrative, with an emphasis on open-source architecture, on-device AI processing, and privacy protection. Halo runs Brilliant Labs' in-house assistant Noa, which supports real-time voice interaction and long-term memory: unlike traditional assistants that start fresh after each exchange, Noa retains conversation context, preferences, and related information, delivering increasingly personalized responses based on long-term habits. Functionality centers on three experiences: Ask, for natural-language Q&A with continuous context; Make, for creating small apps and custom workflows via voice descriptions that can be shared to the Halo app store; and Play, where the Narrative game system brings real life into the experience.Brilliant Labs Unveils Halo AI Glasses With Full-Color Micro-OLED, On-Device AI, and Open-Source ArchitectureOn October 27, Singapore-based smart glasses maker Brilliant Labs unveiled its new Halo AI glasses, priced at $399. The device features a full-color Micro-OLED display, a long-term-memory AI assistant, and an adaptive gaming experience called Narrative, with an emphasis on open-source architecture, on-device AI processing, and privacy protection. Halo runs Brilliant Labs' in-house assistant Noa, which supports real-time voice interaction and long-term memory: unlike traditional assistants that start fresh after each exchange, Noa retains conversation context, preferences, and related information, delivering increasingly personalized responses based on long-term habits. Functionality centers on three experiences: Ask, for natural-language Q&A with continuous context; Make, for creating small apps and custom workflows via voice descriptions that can be shared to the Halo app store; and Play, where the Narrative game system brings real life into the experience.BrilliantHaloLabsRead ↗
Clover-35B-A3B-PreviewDiffuspaceFace Diffuspace/Clover-35B-A3B-Preview · Hugging FaceDiffuspace/Clover-35B-A3B-Preview · Hugging FaceClover-35B-A3B-PreviewDiffuspaceFaceRead ↗
b11951llama.cpp llama.cpp b11951llama.cpp b11951b11951llama.cppRead ↗
LearningQ-learningReleasing Learning RL From Scratch: Releasing 1-page notes on Q-learningLearning RL From Scratch: Releasing 1-page notes on Q-learningLearningQ-learningReleasingRead ↗
resultscodingquality 4B 3D coding model update: much better one-shot results and visual qualityQuick update: I’ve uploaded a new version of my 4B coding model. One-shot results and visual quality are much better in my latest tests, and training is nearly finished. I recommen…4B 3D coding model update: much better one-shot results and visual qualityQuick update: I’ve uploaded a new version of my 4B coding model. One-shot results and visual quality are much better in my latest tests, and training is nearly finished. I recommen…resultscodingqualityRead ↗
DirtGPUscheapDirt cheap GPUs coming next yearDirt cheap GPUs coming next yearDirtGPUscheapRead ↗
BoostInferenceMoE 3 Ways to Boost MoE Inference on NVIDIA DGX Spark3 Ways to Boost MoE Inference on NVIDIA DGX SparkBoostInferenceMoERead ↗
IndexupdateAnalysis Artificial Analysis Intelligence Index v5 (major update)Artificial Analysis Intelligence Index has been updated to v5, which according to them is a major upgrade resulting in a more accurate ranking. Notably, this update widens the gap…Artificial Analysis Intelligence Index v5 (major update)Artificial Analysis Intelligence Index has been updated to v5, which according to them is a major upgrade resulting in a more accurate ranking. Notably, this update widens the gap…IndexupdateAnalysisRead ↗
TPUscommondownWhen will google TPUs trickle down to the common folk?When will google TPUs trickle down to the common folk?TPUscommondownRead ↗
Theydatalab-toindra They released a tesseract successor (datalab-to/indra)They released a tesseract successor (datalab-to/indra)Theydatalab-toindraRead ↗
realtimeserveradd llama.cpp b11946server : add realtime conversation and transcription on /v1/realtime ( #31269 ) server : add realtime conversation and transcription on /v1/realtime Co-authored-by: Xuan Son Nguyen…llama.cpp b11946server : add realtime conversation and transcription on /v1/realtime ( #31269 ) server : add realtime conversation and transcription on /v1/realtime Co-authored-by: Xuan Son Nguyen…realtimeserveraddRead ↗
LiquidAIaddd1-2Bllama.cpp b11945model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B ( #31275 ) model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B Assisted-by: Claude Opus 5.5 convert : keep the speech task templat…llama.cpp b11945model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B ( #31275 ) model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B Assisted-by: Claude Opus 5.5 convert : keep the speech task templat…LiquidAIaddd1-2BRead ↗
llama.cpp b11945model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B ( #31275 ) model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B Assisted-by: Claude Opus 5.5 convert : keep the speech task templat…llama.cpp b11945model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B ( #31275 ) model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B Assisted-by: Claude Opus 5.5 convert : keep the speech task templat…LiquidAIaddd1-2BRead ↗templatechateffortllama.cpp b11944server: expose the reasoning effort levels of the chat template ( #31271 ) server: expose the reasoning effort levels of the chat template The capability probe renders a user turn…llama.cpp b11944server: expose the reasoning effort levels of the chat template ( #31271 ) server: expose the reasoning effort levels of the chat template The capability probe renders a user turn…templatechateffortRead ↗
llama.cpp b11944server: expose the reasoning effort levels of the chat template ( #31271 ) server: expose the reasoning effort levels of the chat template The capability probe renders a user turn…llama.cpp b11944server: expose the reasoning effort levels of the chat template ( #31271 ) server: expose the reasoning effort levels of the chat template The capability probe renders a user turn…templatechateffortRead ↗LiquidAIaddLFM3-Audio-2Bllama.cpp b11941model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B ( #31257 ) model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B Co-authored-by: Xuan Son Nguyen son@huggingface…llama.cpp b11941model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B ( #31257 ) model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B Co-authored-by: Xuan Son Nguyen son@huggingface…LiquidAIaddLFM3-Audio-2BRead ↗
llama.cpp b11941model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B ( #31257 ) model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B Co-authored-by: Xuan Son Nguyen son@huggingface…llama.cpp b11941model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B ( #31257 ) model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B Co-authored-by: Xuan Son Nguyen son@huggingface…LiquidAIaddLFM3-Audio-2BRead ↗DeepSeek-V4.1-Flash-1017tokfull DeepSeek-V4.1-Flash-1017 at 41 tok/s on one 3090No, this is not a lobotomized 1-bit squeeze, its full Q2 nazeshinjite's DeepSeek-V4.1-Flash-1017 Q2 GGUF on a single 3090, natively on Windows no WSL. On an RTX 3090 with 192 GB of…DeepSeek-V4.1-Flash-1017 at 41 tok/s on one 3090No, this is not a lobotomized 1-bit squeeze, its full Q2 nazeshinjite's DeepSeek-V4.1-Flash-1017 Q2 GGUF on a single 3090, natively on Windows no WSL. On an RTX 3090 with 192 GB of…DeepSeek-V4.1-Flash-1017tokfullRead ↗
commondeferredtoolsllama.cpp b11940common : support deferred tools and tool_reference content parts ( #31256 ) common : support deferred tools and tool_reference content parts Assisted-by: Claude Opus 5.5 common : c…llama.cpp b11940common : support deferred tools and tool_reference content parts ( #31256 ) common : support deferred tools and tool_reference content parts Assisted-by: Claude Opus 5.5 common : c…commondeferredtoolsRead ↗
llama.cpp b11940common : support deferred tools and tool_reference content parts ( #31256 ) common : support deferred tools and tool_reference content parts Assisted-by: Claude Opus 5.5 common : c…llama.cpp b11940common : support deferred tools and tool_reference content parts ( #31256 ) common : support deferred tools and tool_reference content parts Assisted-by: Claude Opus 5.5 common : c…commondeferredtoolsRead ↗HynixdemandexpectsSK Hynix expects demand to outpace supply through 2030SK Hynix expects demand to outpace supply through 2030HynixdemandexpectsRead ↗
LiquidAICo-authored-byaddllama.cpp b11938model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B ( #31252 ) model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B Co-authored-by: Sigbjørn Skjæret sigbjorn.skjaeret@huggingf…llama.cpp b11938model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B ( #31252 ) model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B Co-authored-by: Sigbjørn Skjæret sigbjorn.skjaeret@huggingf…LiquidAICo-authored-byaddRead ↗
llama.cpp b11938model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B ( #31252 ) model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B Co-authored-by: Sigbjørn Skjæret sigbjorn.skjaeret@huggingf…llama.cpp b11938model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B ( #31252 ) model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B Co-authored-by: Sigbjørn Skjæret sigbjorn.skjaeret@huggingf…LiquidAICo-authored-byaddRead ↗localbenchmarkleaderboardsI built a local GPU benchmark server for 4B to 35B models because I was tired of synthetic cloud leaderboards and tiny sample testsHi everyone, whenever I looked at existing LLM leaderboards I was missing practical numbers for running quantized open weight models on affordable local hardware. Most tables only…I built a local GPU benchmark server for 4B to 35B models because I was tired of synthetic cloud leaderboards and tiny sample testsHi everyone, whenever I looked at existing LLM leaderboards I was missing practical numbers for running quantized open weight models on affordable local hardware. Most tables only…localbenchmarkleaderboardsRead ↗
audioLFM3-Audio-2Bedge New audio model: LFM3-Audio-2BOne more great model from Liquid AI! Good for edge: LFM3-Audio-2B is a compact, fully featured audio model that runs locally on laptops and edge devices . It takes text or audio as…New audio model: LFM3-Audio-2BOne more great model from Liquid AI! Good for edge: LFM3-Audio-2B is a compact, fully featured audio model that runs locally on laptops and edge devices . It takes text or audio as…audioLFM3-Audio-2BedgeRead ↗
beenscalingtest-time OpenAI's major results over the last 3 months came from scaling test-time compute with agent swarms. I've been building an open-source equivalent for the past year, and I'd love for you guys to try it.I have been working on test-time scaling for quite some time now. Posted some of my previous work on this sub-reddit before . Recently, I made significant simplifications to the co…OpenAI's major results over the last 3 months came from scaling test-time compute with agent swarms. I've been building an open-source equivalent for the past year, and I'd love for you guys to try it.I have been working on test-time scaling for quite some time now. Posted some of my previous work on this sub-reddit before . Recently, I made significant simplifications to the co…beenscalingtest-timeRead ↗
nowreasonComplete The reason why 5090's are $10k now...The reason why 5090's are $10k now...nowreasonCompleteRead ↗
maskselectionsparsellama.cpp b11936llama : build the k-pool sparse selection independently of the kq_mask shape ( #31243 ) llama : build the k-pool sparse selection independently of the kq_mask shape qwen4exp (QSA)…llama.cpp b11936llama : build the k-pool sparse selection independently of the kq_mask shape ( #31243 ) llama : build the k-pool sparse selection independently of the kq_mask shape qwen4exp (QSA)…maskselectionsparseRead ↗
llama.cpp b11936llama : build the k-pool sparse selection independently of the kq_mask shape ( #31243 ) llama : build the k-pool sparse selection independently of the kq_mask shape qwen4exp (QSA)…llama.cpp b11936llama : build the k-pool sparse selection independently of the kq_mask shape ( #31243 ) llama : build the k-pool sparse selection independently of the kq_mask shape qwen4exp (QSA)…maskselectionsparseRead ↗LFM3-Omni-2B-GGUFLiquidAIComplete LiquidAI/LFM3-Omni-2B-GGUFLiquidAI/LFM3-Omni-2B-GGUFLFM3-Omni-2B-GGUFLiquidAICompleteRead ↗
GGUFsLosslessQwen3.8 Statistically Lossless Qwen3.8 27B GGUFsStatistically Lossless Qwen3.8 27B GGUFsGGUFsLosslessQwen3.8Read ↗
Real-timeWebGPUcaptioning Real-time video captioning with LFM3-VL-2B running locally in-browser on WebGPUReal-time video captioning with LFM3-VL-2B running locally in-browser on WebGPUReal-timeWebGPUcaptioningRead ↗
OpenBMBreleasedMiniCPM-OCR OpenBMB released a 1.3B OCR model and a separate 2B model to check its workA PDF turning into clean Markdown doesn't mean all the numbers survived the trip. OpenBMB just released MiniCPM-OCR 1.0, a 1.3B model for parsing Chinese and English documents, alo…OpenBMB released a 1.3B OCR model and a separate 2B model to check its workA PDF turning into clean Markdown doesn't mean all the numbers survived the trip. OpenBMB just released MiniCPM-OCR 1.0, a 1.3B model for parsing Chinese and English documents, alo…OpenBMBreleasedMiniCPM-OCRRead ↗
Ubuntux64macOSllama.cpp b11935rpc : catch std::length_error in recv_msg ( #31204 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60485441 macOS/iOS: macOS Apple Sil…llama.cpp b11935rpc : catch std::length_error in recv_msg ( #31204 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60485441 macOS/iOS: macOS Apple Sil…Ubuntux64macOSRead ↗
llama.cpp b11935rpc : catch std::length_error in recv_msg ( #31204 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60485441 macOS/iOS: macOS Apple Sil…llama.cpp b11935rpc : catch std::length_error in recv_msg ( #31204 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60485441 macOS/iOS: macOS Apple Sil…Ubuntux64macOSRead ↗specializedBuildbringsBuild specialized multimodal models with LFM3LFM3 is our new generation of Liquid Foundation Models (LFMs), built to be the starting point for specialized intelligence. It brings text, vision, audio, omni, and decision models…Build specialized multimodal models with LFM3LFM3 is our new generation of Liquid Foundation Models (LFMs), built to be the starting point for specialized intelligence. It brings text, vision, audio, omni, and decision models…specializedBuildbringsRead ↗
LiquidAIFaceHugging LiquidAI/LFM3-1.7B · Hugging Facehttps://huggingface.co/LiquidAI/LFM3-1.7B-GGUF from liquidAI: LFM3-1.7B is a text model for local agents and specialized applications , based on our new tri-hybrid architecture. Ag…LiquidAI/LFM3-1.7B · Hugging Facehttps://huggingface.co/LiquidAI/LFM3-1.7B-GGUF from liquidAI: LFM3-1.7B is a text model for local agents and specialized applications , based on our new tri-hybrid architecture. Ag…LiquidAIFaceHuggingRead ↗
KinglocalComplete I am a King, but local 😂I am a King, but local 😂KinglocalCompleteRead ↗
MiniCPM-OCRerrorsjudge A 1.3B OCR model just hit 93.68 on real-world document parsing and there's now an AI judge for OCR errorsMost OCR models focus on reading documents. MiniCPM-OCR adds a second piece: a model that checks whether the OCR result is actually trustworthy. OpenBMB just released two open-sour…A 1.3B OCR model just hit 93.68 on real-world document parsing and there's now an AI judge for OCR errorsMost OCR models focus on reading documents. MiniCPM-OCR adds a second piece: a model that checks whether the OCR result is actually trustworthy. OpenBMB just released two open-sour…MiniCPM-OCRerrorsjudgeRead ↗
SystemUpgradeComplete 8x R9700 System Upgrade8x R9700 System UpgradeSystemUpgradeCompleteRead ↗
27 Oct27
tensordatanormalllama.cpp b11934tests : speed up tensor data generation and model saving ( #31145 ) tests : speed up tensor data generation and model saving Refactor save_models to create only the model, not a ll…llama.cpp b11934tests : speed up tensor data generation and model saving ( #31145 ) tests : speed up tensor data generation and model saving Refactor save_models to create only the model, not a ll…tensordatanormalRead ↗
llama.cpp b11934tests : speed up tensor data generation and model saving ( #31145 ) tests : speed up tensor data generation and model saving Refactor save_models to create only the model, not a ll…llama.cpp b11934tests : speed up tensor data generation and model saving ( #31145 ) tests : speed up tensor data generation and model saving Refactor save_models to create only the model, not a ll…tensordatanormalRead ↗Spark-X2.6-1.7Balmostperf Spark-X2.6-1.7B, almost the same perf as 4bSpark-X2.6-1.7B, almost the same perf as 4bSpark-X2.6-1.7BalmostperfRead ↗
broadcastdimmulllama.cpp b11933vulkan: fix CI llvmpipe by allowing dim 3 broadcast in MUL_MAT ( #31239 ) vulkan: allow dim 3 broadcast in MUL_MAT supports_op rejected every MUL_MAT whose src0 and src1 differ in…llama.cpp b11933vulkan: fix CI llvmpipe by allowing dim 3 broadcast in MUL_MAT ( #31239 ) vulkan: allow dim 3 broadcast in MUL_MAT supports_op rejected every MUL_MAT whose src0 and src1 differ in…broadcastdimmulRead ↗
llama.cpp b11933vulkan: fix CI llvmpipe by allowing dim 3 broadcast in MUL_MAT ( #31239 ) vulkan: allow dim 3 broadcast in MUL_MAT supports_op rejected every MUL_MAT whose src0 and src1 differ in…llama.cpp b11933vulkan: fix CI llvmpipe by allowing dim 3 broadcast in MUL_MAT ( #31239 ) vulkan: allow dim 3 broadcast in MUL_MAT supports_op rejected every MUL_MAT whose src0 and src1 differ in…broadcastdimmulRead ↗codeSenseNovavideo SenseNova 6.8 Code2Video: an open-sourced model that writes and revises code to make videosThink of the animation workflows people use with Claude Opus 5.5: the model writes code, rendering tools turn it into video, and further instructions revise the result. SenseNova f…SenseNova 6.8 Code2Video: an open-sourced model that writes and revises code to make videosThink of the animation workflows people use with Claude Opus 5.5: the model writes code, rendering tools turn it into video, and further instructions revise the result. SenseNova f…codeSenseNovavideoRead ↗
BenchmarksCommunityFlash r/LocalLLaMA Community Benchmarks — GLM 5.3 Flash vs Hy 4 Preview vs MiMo v2.6 Pror/LocalLLaMA Community Benchmarks — GLM 5.3 Flash vs Hy 4 Preview vs MiMo v2.6 ProBenchmarksCommunityFlashRead ↗
b11937llama.cpp llama.cpp b11937llama.cpp b11937b11937llama.cppRead ↗
Ubuntumtmd-cliarm64llama.cpp b11932mtmd-cli: Reduced scope of batch pointer ( #31155 ) ( #31165 ) mtmd-cli: Reduced scope of batch pointer ( #31155 ) mtmd-cli: Remove CLI regression test Website: https://llama.app A…llama.cpp b11932mtmd-cli: Reduced scope of batch pointer ( #31155 ) ( #31165 ) mtmd-cli: Reduced scope of batch pointer ( #31155 ) mtmd-cli: Remove CLI regression test Website: https://llama.app A…Ubuntumtmd-cliarm64Read ↗
llama.cpp b11932mtmd-cli: Reduced scope of batch pointer ( #31155 ) ( #31165 ) mtmd-cli: Reduced scope of batch pointer ( #31155 ) mtmd-cli: Remove CLI regression test Website: https://llama.app A…llama.cpp b11932mtmd-cli: Reduced scope of batch pointer ( #31155 ) ( #31165 ) mtmd-cli: Reduced scope of batch pointer ( #31155 ) mtmd-cli: Remove CLI regression test Website: https://llama.app A…Ubuntumtmd-cliarm64Read ↗memoryadddevicellama.cpp b11930server: add router device memory margin parameter for dynamic unloading ( #21231 ) server: add --models-memory-max parameter to allow dynamically unloading models when they exceed…llama.cpp b11930server: add router device memory margin parameter for dynamic unloading ( #21231 ) server: add --models-memory-max parameter to allow dynamically unloading models when they exceed…memoryadddeviceRead ↗
llama.cpp b11930server: add router device memory margin parameter for dynamic unloading ( #21231 ) server: add --models-memory-max parameter to allow dynamically unloading models when they exceed…llama.cpp b11930server: add router device memory margin parameter for dynamic unloading ( #21231 ) server: add --models-memory-max parameter to allow dynamically unloading models when they exceed…memoryadddeviceRead ↗OperaBringingBrowsers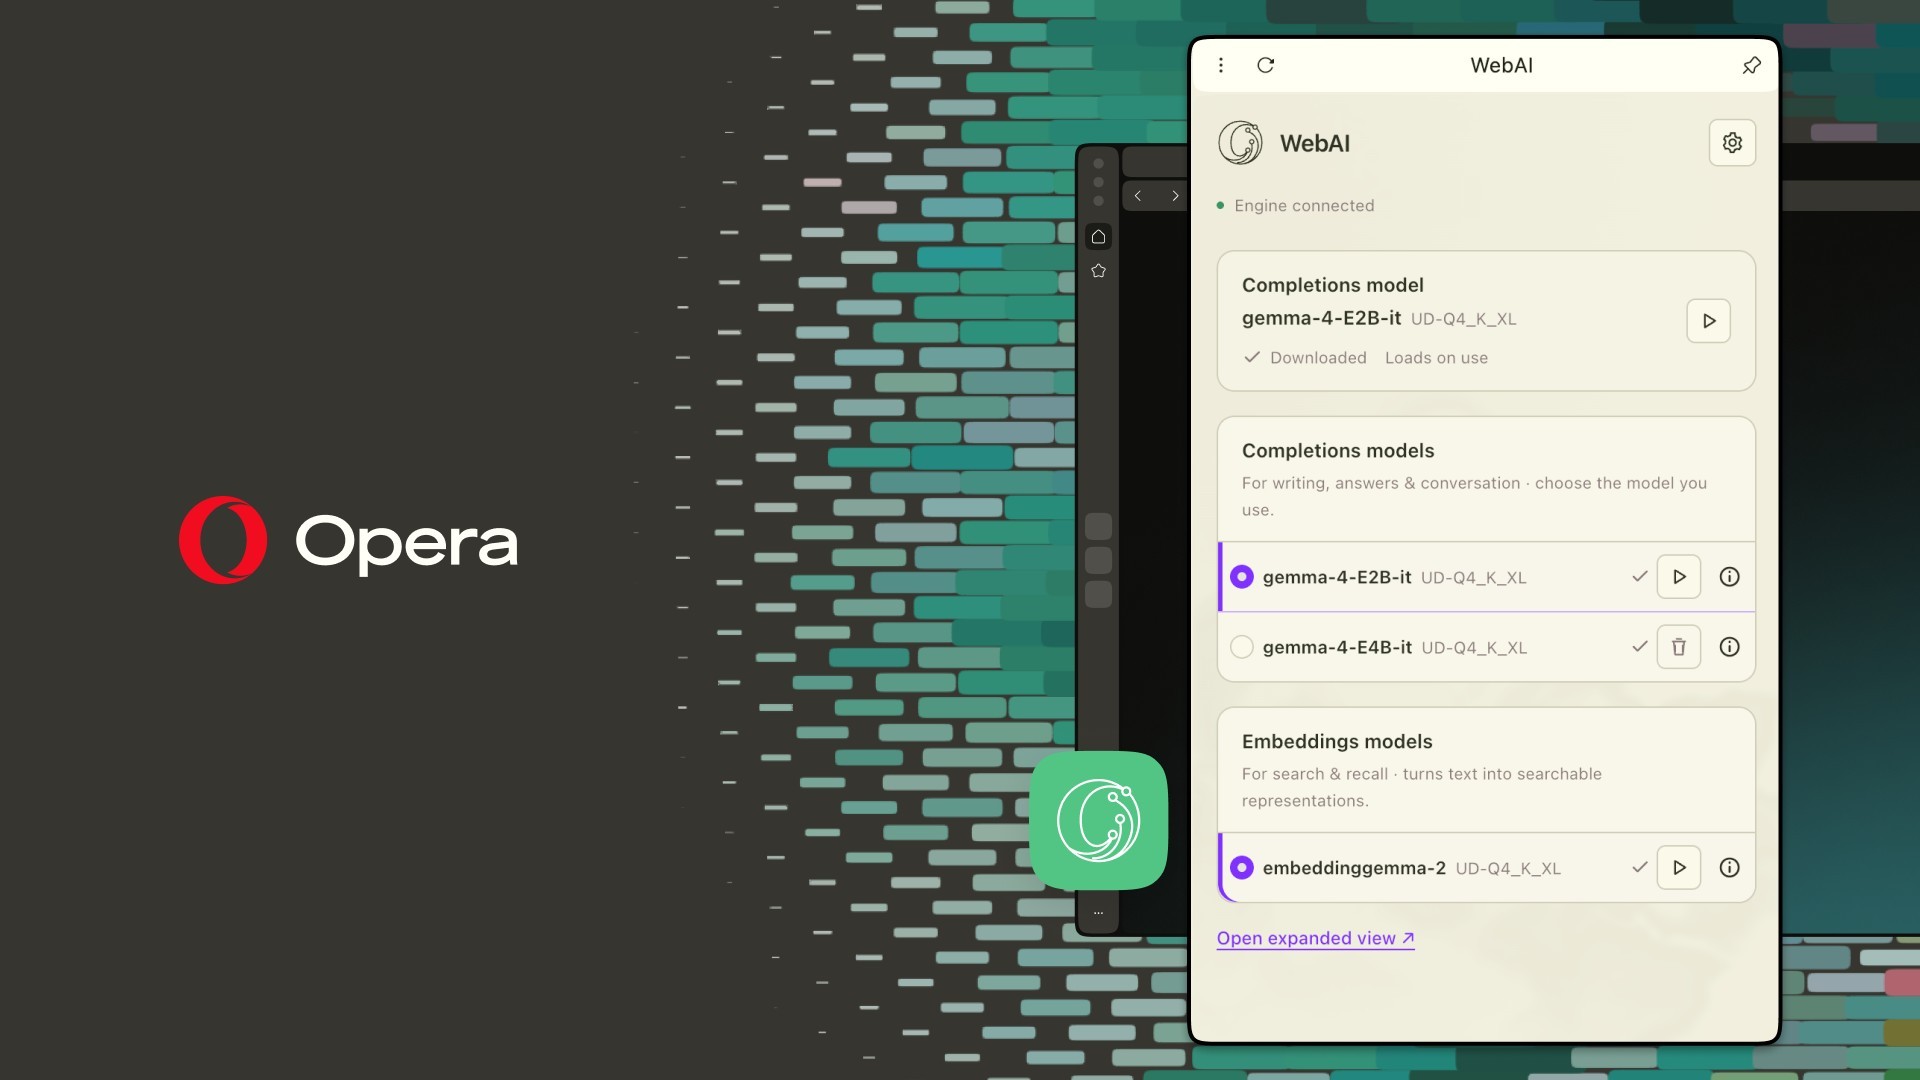 Opera Launches WebAI, Bringing Local AI Models to Its BrowsersOpera announced on October 27, 2026, that it began shipping local AI models directly in its browsers, making AI that runs on a user’s own computer a central part of the next genera…Opera Launches WebAI, Bringing Local AI Models to Its BrowsersOpera announced on October 27, 2026, that it began shipping local AI models directly in its browsers, making AI that runs on a user’s own computer a central part of the next genera…OperaBringingBrowsersRead ↗
tokQwen3.8-27Bagents 4 coding agents on one RTX 3090: ~290 tok/s total from a custom CUDA engine for Qwen3.8-27B (3-4x llama-server --parallel)I've been building OpenJet, a local coding agent with its own CUDA megakernel engine for Qwen3.8-27B Q4_K_M. Until now it served one conversation at a time. The new release serves…4 coding agents on one RTX 3090: ~290 tok/s total from a custom CUDA engine for Qwen3.8-27B (3-4x llama-server --parallel)I've been building OpenJet, a local coding agent with its own CUDA megakernel engine for Qwen3.8-27B Q4_K_M. Until now it served one conversation at a time. The new release serves…tokQwen3.8-27BagentsRead ↗
Ubuntux64arm64llama.cpp b11929common : --model or -hf is required ( #31242 ) Assisted-by: Codex Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60378927 macOS/iOS: ma…llama.cpp b11929common : --model or -hf is required ( #31242 ) Assisted-by: Codex Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60378927 macOS/iOS: ma…Ubuntux64arm64Read ↗
llama.cpp b11929common : --model or -hf is required ( #31242 ) Assisted-by: Codex Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60378927 macOS/iOS: ma…llama.cpp b11929common : --model or -hf is required ( #31242 ) Assisted-by: Codex Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/60378927 macOS/iOS: ma…Ubuntux64arm64Read ↗theyweightsLing-3.1-flash-1019 Ling-3.1-flash-1019 weights are out, and they released the base model tooWell, “coming soon” turned out to be five days. I posted the earlier announcement last week. The 1019 weights are now on Hugging Face . Still 560B total, 25B active, with a 1M cont…Ling-3.1-flash-1019 weights are out, and they released the base model tooWell, “coming soon” turned out to be five days. I posted the earlier announcement last week. The 1019 weights are now on Hugging Face . Still 560B total, 25B active, with a 1M cont…theyweightsLing-3.1-flash-1019Read ↗
MiniCPM-OCR-JevAddb11928llama.cpp b11928model: Add MiniCPM-OCR-Jev ( #30980 ) model : add MiniCPM-OCR-Jev support The model is a Qwen3.5-VL trunk with a value head read at the last token: it scores an OCR text against an…llama.cpp b11928model: Add MiniCPM-OCR-Jev ( #30980 ) model : add MiniCPM-OCR-Jev support The model is a Qwen3.5-VL trunk with a value head read at the last token: it scores an OCR text against an…MiniCPM-OCR-JevAddb11928Read ↗
llama.cpp b11928model: Add MiniCPM-OCR-Jev ( #30980 ) model : add MiniCPM-OCR-Jev support The model is a Qwen3.5-VL trunk with a value head read at the last token: it scores an OCR text against an…llama.cpp b11928model: Add MiniCPM-OCR-Jev ( #30980 ) model : add MiniCPM-OCR-Jev support The model is a Qwen3.5-VL trunk with a value head read at the last token: it scores an OCR text against an…MiniCPM-OCR-JevAddb11928Read ↗QwenBubblinaDesktopBest way to use R9700 vs RTX3060 or RTX3090 for QwenThoughts on how I might best use my hardware? MiniPC (Bubblina) with eGPU oculink R9700 (32GB AMD) 64GB DDR5 - Qwen3.8-27B Paiton-KV4-vision 262K context, 8-concurrent Desktop (BM1…Best way to use R9700 vs RTX3060 or RTX3090 for QwenThoughts on how I might best use my hardware? MiniPC (Bubblina) with eGPU oculink R9700 (32GB AMD) 64GB DDR5 - Qwen3.8-27B Paiton-KV4-vision 262K context, 8-concurrent Desktop (BM1…QwenBubblinaDesktopRead ↗
bpwISTA-DASLabagainstComparing ISTA-DASLab's DeepSeek-V4.1-Flash-1017-GSQ-RCO-GGUF 2.25bpw against the official APII've been running ISTA-DASLab's 2.25bpw quant of DSv4.1-1017 for a few days, and it's holding up well. But the fact that it's only 2.25bpw average did make me wonder how good the q…Comparing ISTA-DASLab's DeepSeek-V4.1-Flash-1017-GSQ-RCO-GGUF 2.25bpw against the official APII've been running ISTA-DASLab's 2.25bpw quant of DSv4.1-1017 for a few days, and it's holding up well. But the fact that it's only 2.25bpw average did make me wonder how good the q…bpwISTA-DASLabagainstRead ↗
Ling-3.1-flash-1019inclusionAIparameters inclusionAI/Ling-3.1-flash-1019 · Hugging Facefrom inclusionAI: We introduce Ling-3.1-flash-1019 , an upgraded version of Ling-3.1-flash , with 560B total parameters, 25B active parameters per token, and a 1M-token context win…inclusionAI/Ling-3.1-flash-1019 · Hugging Facefrom inclusionAI: We introduce Ling-3.1-flash-1019 , an upgraded version of Ling-3.1-flash , with 560B total parameters, 25B active parameters per token, and a 1M-token context win…Ling-3.1-flash-1019inclusionAIparametersRead ↗
llama.cppmetaladdllama.cpp b11927metal : add GGML_OP_TOP_K_MASK ( #31230 ) metal : add GGML_OP_TOP_K_MASK Port the fused top-k mask from the CUDA backend: a grid-stride kernel fills the output with -inf, then one…llama.cpp b11927metal : add GGML_OP_TOP_K_MASK ( #31230 ) metal : add GGML_OP_TOP_K_MASK Port the fused top-k mask from the CUDA backend: a grid-stride kernel fills the output with -inf, then one…llama.cppmetaladdRead ↗
llama.cpp b11927metal : add GGML_OP_TOP_K_MASK ( #31230 ) metal : add GGML_OP_TOP_K_MASK Port the fused top-k mask from the CUDA backend: a grid-stride kernel fills the output with -inf, then one…llama.cpp b11927metal : add GGML_OP_TOP_K_MASK ( #31230 ) metal : add GGML_OP_TOP_K_MASK Port the fused top-k mask from the CUDA backend: a grid-stride kernel fills the output with -inf, then one…llama.cppmetaladdRead ↗Trydflash2draftUsing Q38FN with dflash2? Try lower draft model quants.Using Q38FN with dflash2? Try lower draft model quants.Trydflash2draftRead ↗
Ubuntumaskarm64llama.cpp b11926glm5-next : QSA without kq_mask (+ DSA) ( #31009 ) glm5-next : QSA without kq_mask DSA: dsa top-k mask change tested with layers 0,3 of DeepSeek-V3.2 Website: https://llama.app Att…llama.cpp b11926glm5-next : QSA without kq_mask (+ DSA) ( #31009 ) glm5-next : QSA without kq_mask DSA: dsa top-k mask change tested with layers 0,3 of DeepSeek-V3.2 Website: https://llama.app Att…Ubuntumaskarm64Read ↗
llama.cpp b11926glm5-next : QSA without kq_mask (+ DSA) ( #31009 ) glm5-next : QSA without kq_mask DSA: dsa top-k mask change tested with layers 0,3 of DeepSeek-V3.2 Website: https://llama.app Att…llama.cpp b11926glm5-next : QSA without kq_mask (+ DSA) ( #31009 ) glm5-next : QSA without kq_mask DSA: dsa top-k mask change tested with layers 0,3 of DeepSeek-V3.2 Website: https://llama.app Att…Ubuntumaskarm64Read ↗modelsreverseAnything We put DeepSeek in charge of four Qwen3.5-9B models to reverse engineer binaries using smaller open models.Reverse Engineer Anything blew up recently but, every impressive reverse engineering result we’ve seen uses (closed) frontier models. We wanted to know whether small local models c…We put DeepSeek in charge of four Qwen3.5-9B models to reverse engineer binaries using smaller open models.Reverse Engineer Anything blew up recently but, every impressive reverse engineering result we’ve seen uses (closed) frontier models. We wanted to know whether small local models c…modelsreverseAnythingRead ↗
idstokenAlibabaDebunking Cohere's claim of Qwen 3.8 Flash Next uploading to Alibaba remote URLHF traces: https://huggingface.co/datasets/CohereLabs/10-2026-qwen-investigation-traces 1. Understand the Python script: ids ids = dataset[0]["token_ids"] if len(ids) < 2323: raise…Debunking Cohere's claim of Qwen 3.8 Flash Next uploading to Alibaba remote URLHF traces: https://huggingface.co/datasets/CohereLabs/10-2026-qwen-investigation-traces 1. Understand the Python script: ids ids = dataset[0]["token_ids"] if len(ids) < 2323: raise…idstokenAlibabaRead ↗
PCIeGoodResults Tensor Split Over PCIe 3.0 x1 — Good ResultsWhen I was considering adding a second GPU, quite a few people told me PCIe 3.0 x1 would be a massive bottleneck and that upgrading my motherboard should be my first priority. I we…Tensor Split Over PCIe 3.0 x1 — Good ResultsWhen I was considering adding a second GPU, quite a few people told me PCIe 3.0 x1 would be a massive bottleneck and that upgrading my motherboard should be my first priority. I we…PCIeGoodResultsRead ↗
llama.cppmanagergraphical I made Pumpkin, a graphical manager for llama.cpp for my girlfriend. It turned out well, so I put it on githubAs the title says, my girlfriend needed a local model for privacy reasons, but her terminal skills are... nonexistent, so I made an all-in-one graphical manager for llama.cpp that…I made Pumpkin, a graphical manager for llama.cpp for my girlfriend. It turned out well, so I put it on githubAs the title says, my girlfriend needed a local model for privacy reasons, but her terminal skills are... nonexistent, so I made an all-in-one graphical manager for llama.cpp that…llama.cppmanagergraphicalRead ↗
FaceHuggingUnlimited-OCR-2 baidu/Unlimited-OCR-2 · Hugging FaceRelease [2026/10/27] 🚀 We release Unlimited OCR 2 , achieving unlimited-horizon parsing with SR-SWA. What's New in 2 Sparse Reference Sliding Window Attention (SR-SWA): Compresses…baidu/Unlimited-OCR-2 · Hugging FaceRelease [2026/10/27] 🚀 We release Unlimited OCR 2 , achieving unlimited-horizon parsing with SR-SWA. What's New in 2 Sparse Reference Sliding Window Attention (SR-SWA): Compresses…FaceHuggingUnlimited-OCR-2Read ↗
ggmlscalerelaxllama.cpp b11923ggml : relax scale to non-contiguous views ( #31146 ) ggml : relax scale to non-contiguous views SCALE requires src0 to be 1D-contiguous. Relax this to dim-0 contiguity with arbitr…llama.cpp b11923ggml : relax scale to non-contiguous views ( #31146 ) ggml : relax scale to non-contiguous views SCALE requires src0 to be 1D-contiguous. Relax this to dim-0 contiguity with arbitr…ggmlscalerelaxRead ↗
llama.cpp b11923ggml : relax scale to non-contiguous views ( #31146 ) ggml : relax scale to non-contiguous views SCALE requires src0 to be 1D-contiguous. Relax this to dim-0 contiguity with arbitr…llama.cpp b11923ggml : relax scale to non-contiguous views ( #31146 ) ggml : relax scale to non-contiguous views SCALE requires src0 to be 1D-contiguous. Relax this to dim-0 contiguity with arbitr…ggmlscalerelaxRead ↗b11925llama.cpp llama.cpp b11925llama.cpp b11925b11925llama.cppRead ↗
llama.cppUbuntumacOSllama.cpp b11921llama : remove obsolete n_pad from memory instances ( #31200 ) Every caller passes n_pad = 1 and the only two users clamp it to 256. Drop the parameter, the members and the trivial…llama.cpp b11921llama : remove obsolete n_pad from memory instances ( #31200 ) Every caller passes n_pad = 1 and the only two users clamp it to 256. Drop the parameter, the members and the trivial…llama.cppUbuntumacOSRead ↗
llama.cpp b11921llama : remove obsolete n_pad from memory instances ( #31200 ) Every caller passes n_pad = 1 and the only two users clamp it to 256. Drop the parameter, the members and the trivial…llama.cpp b11921llama : remove obsolete n_pad from memory instances ( #31200 ) Every caller passes n_pad = 1 and the only two users clamp it to 256. Drop the parameter, the members and the trivial…llama.cppUbuntumacOSRead ↗